Same Run Differential, Different Win Rate: Defining "Luck" with Pythagorean Expectation
I closed the last post with this question.
If run differential alone leaves something on the table, is there a better formula for win rate?
After confirming r = 0.95 across 5 seasons and 150 teams, we asked where the rest — the gap between 0.95 and 1 — was coming from. Two teams with the same run differential can end up with different win rates. A +50 from "winning 6–5 a lot" looks the same on paper as a +50 from "one 10–0 win and two 1–0 losses," but the win rates are different.
So if we take a formula that uses RS and RA separately — not just RS − RA — could it close that gap?
It turns out the baseball stats world already has one.
Meet Bill James
In the late 1970s, Bill James was working night shifts as a security guard at a pork-and-beans cannery in Kansas when he started writing about baseball. He wasn't part of a team or a university.
That's Bill James. He started self-publishing the Baseball Abstract in 1977 and gave the statistical study of baseball its name: sabermetrics. The data-driven approach of the Oakland A's, made famous by Moneyball, came out of that tradition.
One of the formulas he proposed is the topic of this post. Here's the form.
In words: square the runs scored, divide by (RS² + RA²). The result lands between 0 and 1, and James argued it would be close to that team's actual win rate.
It's called Pythagorean Expectation, because the formula's shape — squares on top and bottom — resembles a² + b² = c².
Why Squared?
A natural question here: Why square RS and RA? Why not just use them?
The simpler ratio RS / (RS + RA) comes out too gentle compared to actual win rates — it underestimates good teams and overestimates bad ones.
Pushing the exponent up to 2 — RS² / (RS² + RA²) — pulled the predictions further apart in both directions. Good teams got pushed up, bad teams got pushed down. That fit better.
Intuitive read: squaring widens the ratio between the two numbers — a 1.5× gap becomes 2.25×. A team with RS=900 and RA=600 gets a simple-ratio score of about 0.6 but a Pythagorean score of 810,000 / (810,000 + 360,000) ≈ 0.69. That extra 0.09 captures something real about baseball: bigger run advantages come with disproportionately bigger win rates. It's nonlinear.
The formula was found by checking which shape fit baseball data. The name borrows from a Greek mathematician, but it's empirical.
Plugging It Into 5 Seasons
The real question is whether this works on our data. So I pulled RS and RA for all 150 team-seasons in 2021–2025, computed the Pythagorean expected win rate for each, and put them on a scatter plot.
X-axis: Pythagorean expectation. Y-axis: actual win rate. Plus a y=x reference line. If a point sits exactly on that line, the formula got it exactly right.
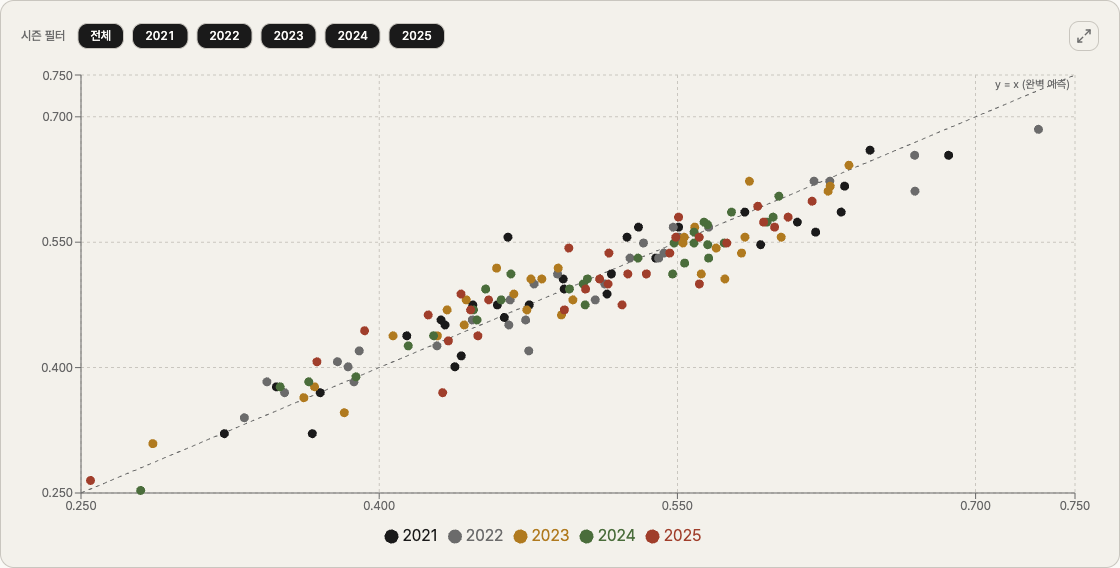
You can see the answer already: the points sit close to the diagonal. There's some scatter above and below, but very few points stray far.
And Yet… r Barely Moved
Let's get the number out of the way. In Q1, we got r(Diff, Pct) = 0.95. What does r(Pythagorean, Pct) look like?
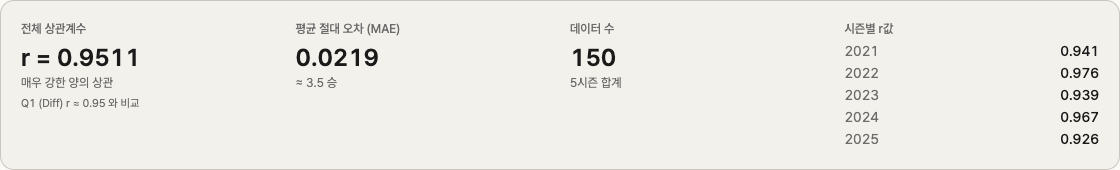
Across 150 points, r = 0.9511. Compared to Q1's 0.9503… that's a 0.0008 improvement. Practically nothing.
Honestly, that's smaller than expected. We came in expecting "smarter formula → r jumps." Instead, a squared ratio barely beats simple subtraction.
Here's why. r measures how much two variables move together. As we saw in Q1, run diff and win rate are tied together by definition. Hitting 0.95 already means "the linear relationship explains almost everything." A fancier formula has little room left to raise r.
So is Pythagorean useless? By r alone it looks that way, but a different measure tells a different story.
Looking at the residual
What Pythagorean actually gives us is a concrete predicted win rate per team. Q1's r = 0.95 was a one-line fact about a relationship; Pythagorean gives you, for every team, a number that says "based on RS and RA, this team should win about 58.4%."
Once you have a prediction, you can compute the residual.
Residual = actual win rate − Pythagorean expected win rate
Two teams with the same RS and RA might have residuals of +0.04 and −0.04. Same runs, same prevention, but they ended up 8 percentage points apart. Where did the gap come from? From everything the formula doesn't capture — how the runs were distributed across games, plus luck.
Phrased differently: we now have a way to split win rate into "what the formula explains" and "what it doesn't."
How Many Wins Off, On Average?
That leads to the next question.
How big is this miss, on average?
The standard tool is MAE (Mean Absolute Error) — average the absolute values of the residuals so positive and negative don't cancel out.
Across 5 seasons, MAE = 0.0219. That's in win-rate units, which is hard to feel. Convert it.
0.0219 × 162 games ≈ 3.55 wins
So Pythagorean is off by about 3.5 wins per team-season, on average. If the formula says a team "should win 85," reality usually lands somewhere between 81 and 89.
In a 162-game season, 3.5 wins is roughly 2%. With just RS and RA, you can predict a team's win total to within about 3.5 wins on average.
The move from 0.9503 to 0.9511 in r was small, but seen this way the formula is clearly useful: on top of "they move together," we can now say "RS and RA alone predict wins to within about 3.5 on average."
"Lucky" Teams and "Unlucky" Teams
Let's see who shows up at the top and bottom of the list.
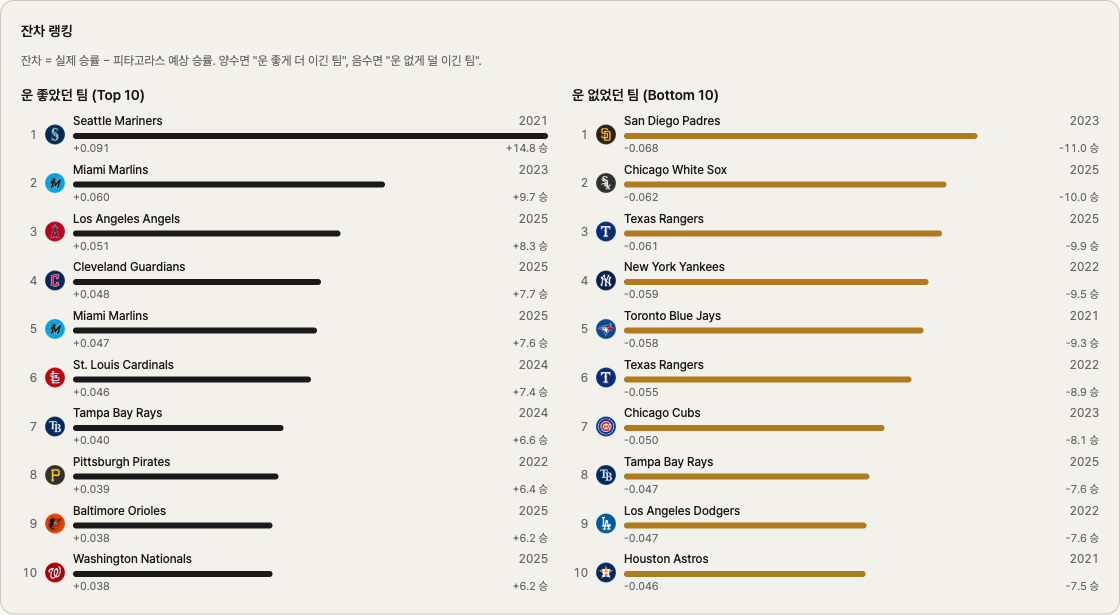
The team that outperformed Pythagorean the most (largest positive residual — "luckiest") across 5 seasons is this one.
2021 Mariners: residual +0.091, about +14.8 wins
By RS and RA alone, the 2021 Mariners looked like a 46.5% team — call it 75 wins. They actually finished 90–72. Fifteen wins more than the formula expected.
On the other side, the team that underperformed Pythagorean the most is this one.
2023 Padres: residual −0.068, about −11 wins
By RS and RA, the 2023 Padres were a 57.4% team — about 93 wins. They actually finished 82–80, missing the wild card entirely. This is the team that fielded Manny Machado, Juan Soto, and Xander Bogaerts in the same lineup — a preseason contender. By RS and RA alone, they should have won 11 more.
Measured against the formula, the two teams are about 25 wins apart. That's how wide residuals can get.
Be Careful With the Word "Luck"
One honest caveat. A residual of +0.091 isn't all pure luck.
Stuff Pythagorean misses bundles together several things:
- Skill at winning close games: a great closer, clutch hitters, a sharp manager
- Injury timing: losing four starters in August vs. staying healthy
- Schedule strength: who you happened to play often
- Pure randomness: closing 14 one-run games at 9–5 vs. 7–7
Some of that is "skill" and some is "luck," and data alone can't separate them.
So instead of saying "this team got lucky," it's safer to say "this team has something the formula doesn't capture." If that something is real skill, the residual will stay positive next year. If it's luck, it'll regress. Telling those apart is a whole separate analysis.
Re-reading Q1
Loop back to Q1 for a second. We saw r = 0.95 and noted the gap to 1. We said "two teams with the same run diff can have different win rates."
After Pythagorean, that gap is clearer.
- Part of it comes from how the runs were distributed. Pythagorean catches that — it's the small move in r from 0.9503 to 0.9511.
- The remaining residual is harder to pin down. That's the close-game stuff, injuries, schedule. About ±3.5 wins per season on average.
The Next Question
One more question. Bill James used 2 as the exponent. It was found empirically — but is 2 really the best?
Some baseball analysts use 1.83 instead. Who's right?
Is 2.0 actually the right exponent? Can we find the real best from the data?
That's the next post. I'll sweep every exponent from 1.5 to 2.5 in 0.01 steps, find the one that minimizes MAE, and check whether the answer is the same every season.
This analysis was done with just-mlb, a tool I built. Look at the Q2 scatter and the residual ranking yourself, and find out whether your team has been "lucky" or "unlucky" by Pythagorean.

